AI SEO In Detail › Module A · Foundations › Episode 3
DataForSEO API from zero: your first call
Set up a DataForSEO account, test for free in the sandbox, make your first paid live SERP call, read the JSON and cache the response so you never pay twice. Free first-call kit.
Playing the video loads it from YouTube (privacy-enhanced mode).
DataForSEO First Call Starter Script
A small Python starter script for DataForSEO: credentials from environment variables, a free balance check, one live results-page request with a cost prompt, status codes checked per task, and the raw response cached before it is parsed into SQLite.
- Credentials outside the project — Put your API login and API password in a private file in your home folder and load them as environment variables. The script never contains them.
- Free check, then sandbox — Run the free balance call to prove your credentials work, then build and test your parsing against the sandbox, which returns dummy data and is not billed.
- One live call, cached — The script shows the estimated cost, asks for a yes, saves the raw JSON before parsing and writes one row per result to SQLite. Re-runs read the cache for free.
Python 3.9+ · standard library only · no keys included · no sign-up
Full transcript
1,035 words · the narration as spoken in the episode.
Intro
The DataForSEO documentation has hundreds of endpoints. You open it, you scroll, and an hour later you still haven't made a single request.
You don't need hundreds of endpoints. To start, you need three things: credentials that are stored safely, one free call to check that everything works, and one paid call that returns something useful.
In this episode we go from a new account to a live results page in Python, read the response, and save it so we never pay for it twice.
Account and credentials
First, the account. You sign up, add a small deposit, and the API is pay as you go. No monthly plan. Every call is billed from your balance.
In the dashboard you'll find your API login and an API password. Note that the API password is not the one you use to log in to the website. The API uses basic authentication: login and API password on every request.
Now, the most important habit of this episode. Those credentials never go into your script. Not in the code, not in a notebook, not in a chat with an AI assistant.
I keep them in a small environment file in my home folder, outside every project, readable only by my own user. The script reads two environment variables at runtime. That way the project folder can be shared, synced or put in version control without leaking a key. If a key does leak, you change the API password in the dashboard, and the old one stops working.
Sandbox vs live, and a free first call
DFS has a sandbox. Same endpoints, same request format, but a different hostname, and it returns dummy data without charging you. Use it while you're writing your parsing code. You can hammer it as much as you like.
Then, before you spend anything on the live API, make one free call there. The user data endpoint returns your account details, including your current balance. It costs nothing.
If that call works, your credentials work. And I use it for something else too: I check the balance before every big run, instead of trusting a number I wrote down last week. It takes one second and it's free.
The first paid call: a live results page
Now the real thing. We ask for the live Google results page for one keyword. The endpoint is the organic live advanced endpoint, under SERP, Google.
The request body is a small list of tasks. Each task has a keyword, a location, a language, and a depth, which is how many results you want. Location and language matter a lot. The same keyword gives different results in different countries, so always set them explicitly.
Depth ten means the first page. In my own billing, that's about three tenths of a cent.
The call takes a few seconds, because it's live: DFS fetches the page right then. And here's our response.
Reading the JSON
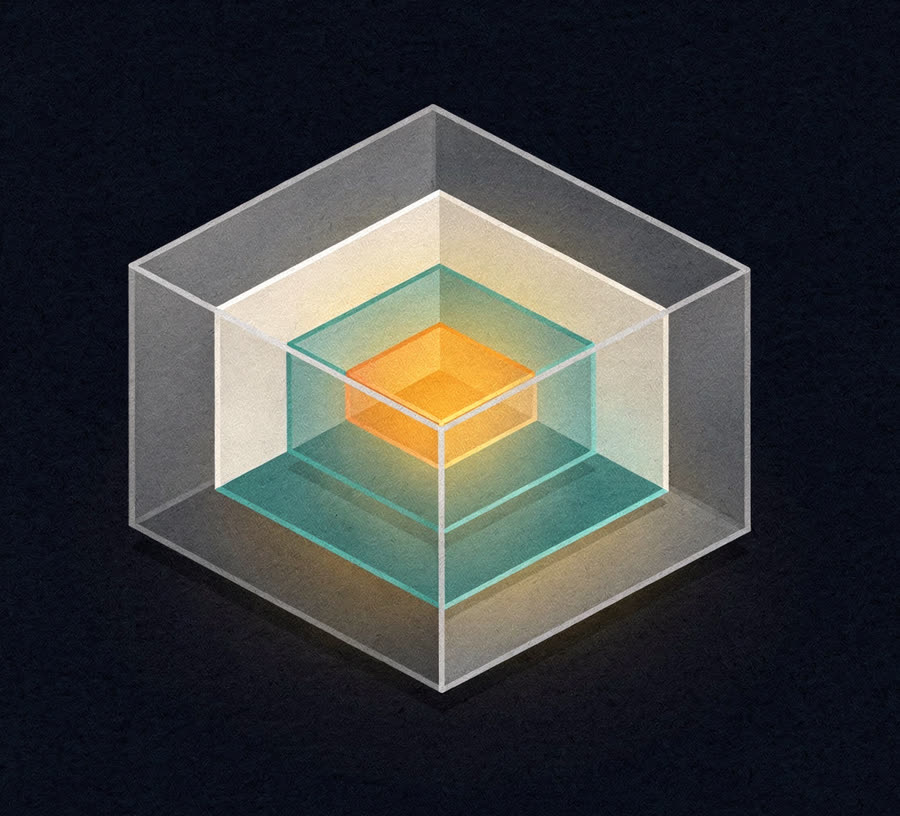
The response looks big, but it's four levels deep, and you only need to know those four.
At the top, a status code and a cost for the whole request. Then a list of tasks, one per task you sent, each with its own status code. Inside each task, a result. And inside the result, a list called items. That's the results page.
Each item has a type. "Organic" is a normal blue link. But you'll also see types for featured snippets, "People also ask", local packs, videos and so on. Each item has a position on the page, a domain, a URL and a title.
One detail that confuses people: there are two rank numbers. One counts every element on the page, features included. The other counts only within the same type, so the first organic result is number one among organic results, even if a snippet and a map sit above it. Decide which one your analysis uses, and stick to it.
So the first parsing rule is simple: loop through the items, and always look at the type before you read anything else. We'll go much deeper into features in episode twenty-eight.
Live vs task mode, and error codes
What we just did is live mode: one request, one answer. DFS also has task mode. You post the tasks, they're queued, and you collect the results later. It's cheaper per request and fine for big batches where you don't need the answer right now. For learning and for small checks, live is simpler.
Errors. Every response has a status code. Twenty thousand means OK. Codes in the forty thousand range mean something is wrong with your request, like a bad parameter, or a balance that's run out. Fifty thousand range means a problem on their side. Check the status code on every task, not only on the whole response. A request can succeed while one task inside it fails.
Cache the response
Last step, and it's the one that saves the most money. Before you parse anything, save the raw response to disk. One file per keyword, location, language, depth and date, so the file name tells you exactly what's inside.
Then write your script so it checks the cache first. If the file exists, read it. If not, make the paid call and save it. Now a crash in your parsing code costs nothing, and you can rerun your analysis as many times as you like.
It also gives you history. A folder of saved results pages is a time series you can compare later.
From JSON to a table row
The cached file is the source of truth. But for analysis, you want rows, not nested JSON.
So the parser does one job. For each item, it writes one row: the date, the keyword, the location and device you asked for, the rank, the type, the domain, the URL and the title. Nothing else is decided at this stage. No filtering, no scoring.
That table is the SERP part of the data model we'll build in episode five. Because you kept the raw file, you can always add a column later, like a feature you didn't care about today, by parsing the cache again. No new call, no new cost.
Wrap-up
Credentials outside the project, a free check first, one live call, and cache before you parse. The starter script is linked in the description. Next episode: pulling your own data from the Search Console API. See you there.